AuraTalk AI — Emotion-Aware Real-Time AI Avatar Platform
PROJECT TYPE
Internal R&D Prototype
NEURAL PIPELINE
CUDA Wav2Lip Lip-Sync
VISION & AI
MediaPipe Vision + Local Llama 3
STREAMING & UI
FastAPI WebSockets & Glassmorphism
Interactive video assistant platform built with FastAPI, WebSockets, MediaPipe computer vision, and local LLM inference.
AuraTalk AI combines computer vision, Wav2Lip neural lip-synchronization, and local Large Language Models (LLM) to deliver dynamic, context-aware conversations.
Powered by CUDA-accelerated Wav2Lip neural lip-sync, local LLM intelligence, Edge-TTS audio synthesis, and MediaPipe computer vision for real-time user emotion analysis.
CUDA-Accelerated Neural Lip-Sync Engine
Integrates PyTorch and custom CUDA-optimized Wav2Lip inference pipeline. Generates synchronized facial animation aligned frame-by-frame with synthesized audio using CUDA acceleration.
Procedural Micro-Animation & Lifetime Engine
Procedural micro-animation introducing natural facial sway, breathing cycles, and blink intervals with dynamic landmark-aware mesh alignment.
Real-Time Computer Vision & User Emotion Tracking
Powered by Google MediaPipe Tasks Face Landmarker running via camera feed. Detects live user sentiment (Happy, Empathetic, Neutral, Surprised, Sad) and adapts avatar tone & visual brightness.
Emotion-Contextual LLM Memory Engine
Custom Local Llama AI integration with multi-turn conversation memory. Adjusts conversational context dynamically based on detected user emotional sentiment for relevant, context-aware responses.
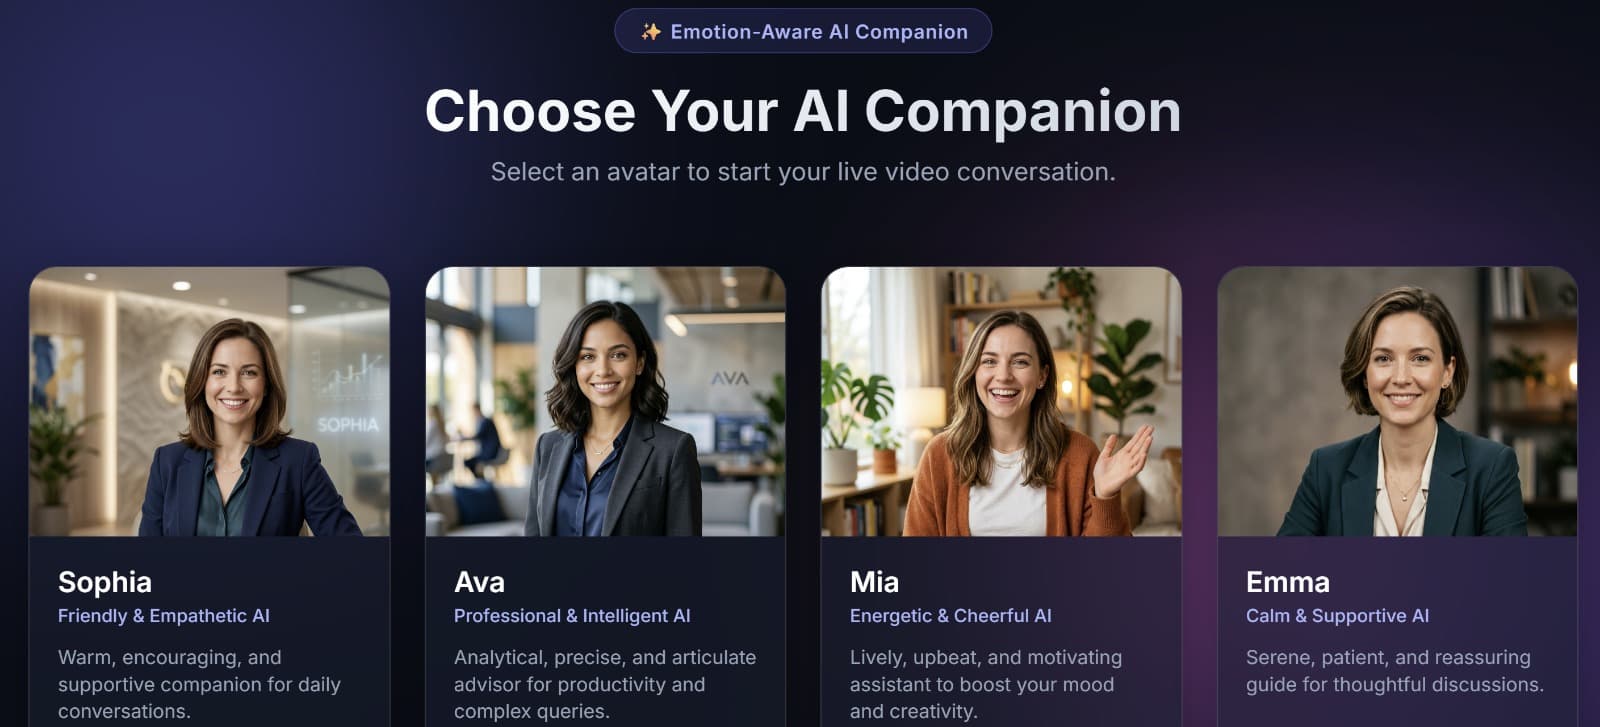
Multi-Persona Avatar System
5 pre-calibrated high-definition female AI avatars tuned for distinct conversational roles: Sophia, Ava, Mia, Emma, and Luna.
Full-Duplex WebAudio Voice Activity Detection (VAD)
Automatic voice boundary detection with intelligent silence thresholding for seamless hands-free speech input with integrated text fallback mode.
Ultra-Modern Glassmorphic Dark Call UI
Premium Web App interface featuring real-time state feedback rings, animated emotion badges, live transcript drawer, and dual video PIP views.
Sophia
Friendly & Empathetic Companion
Ava
Professional & Intelligent Advisor
Mia
Energetic & Cheerful AI
Emma
Calm & Supportive Guide
Luna
Creative & Witty Conversationalist